ARTIFICIAL INTELLIGENCE SYSTEM
Private persistent agent
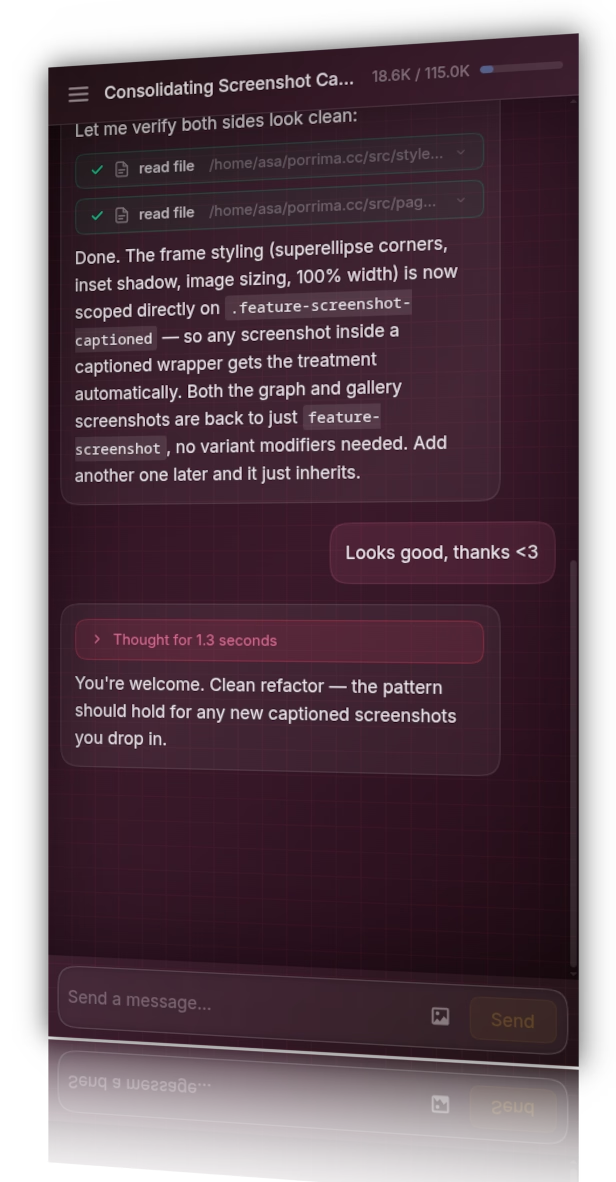
Self-host and access remotely, full feature set on all devices
Webauthn passkey security
Theme and style options to make it your own
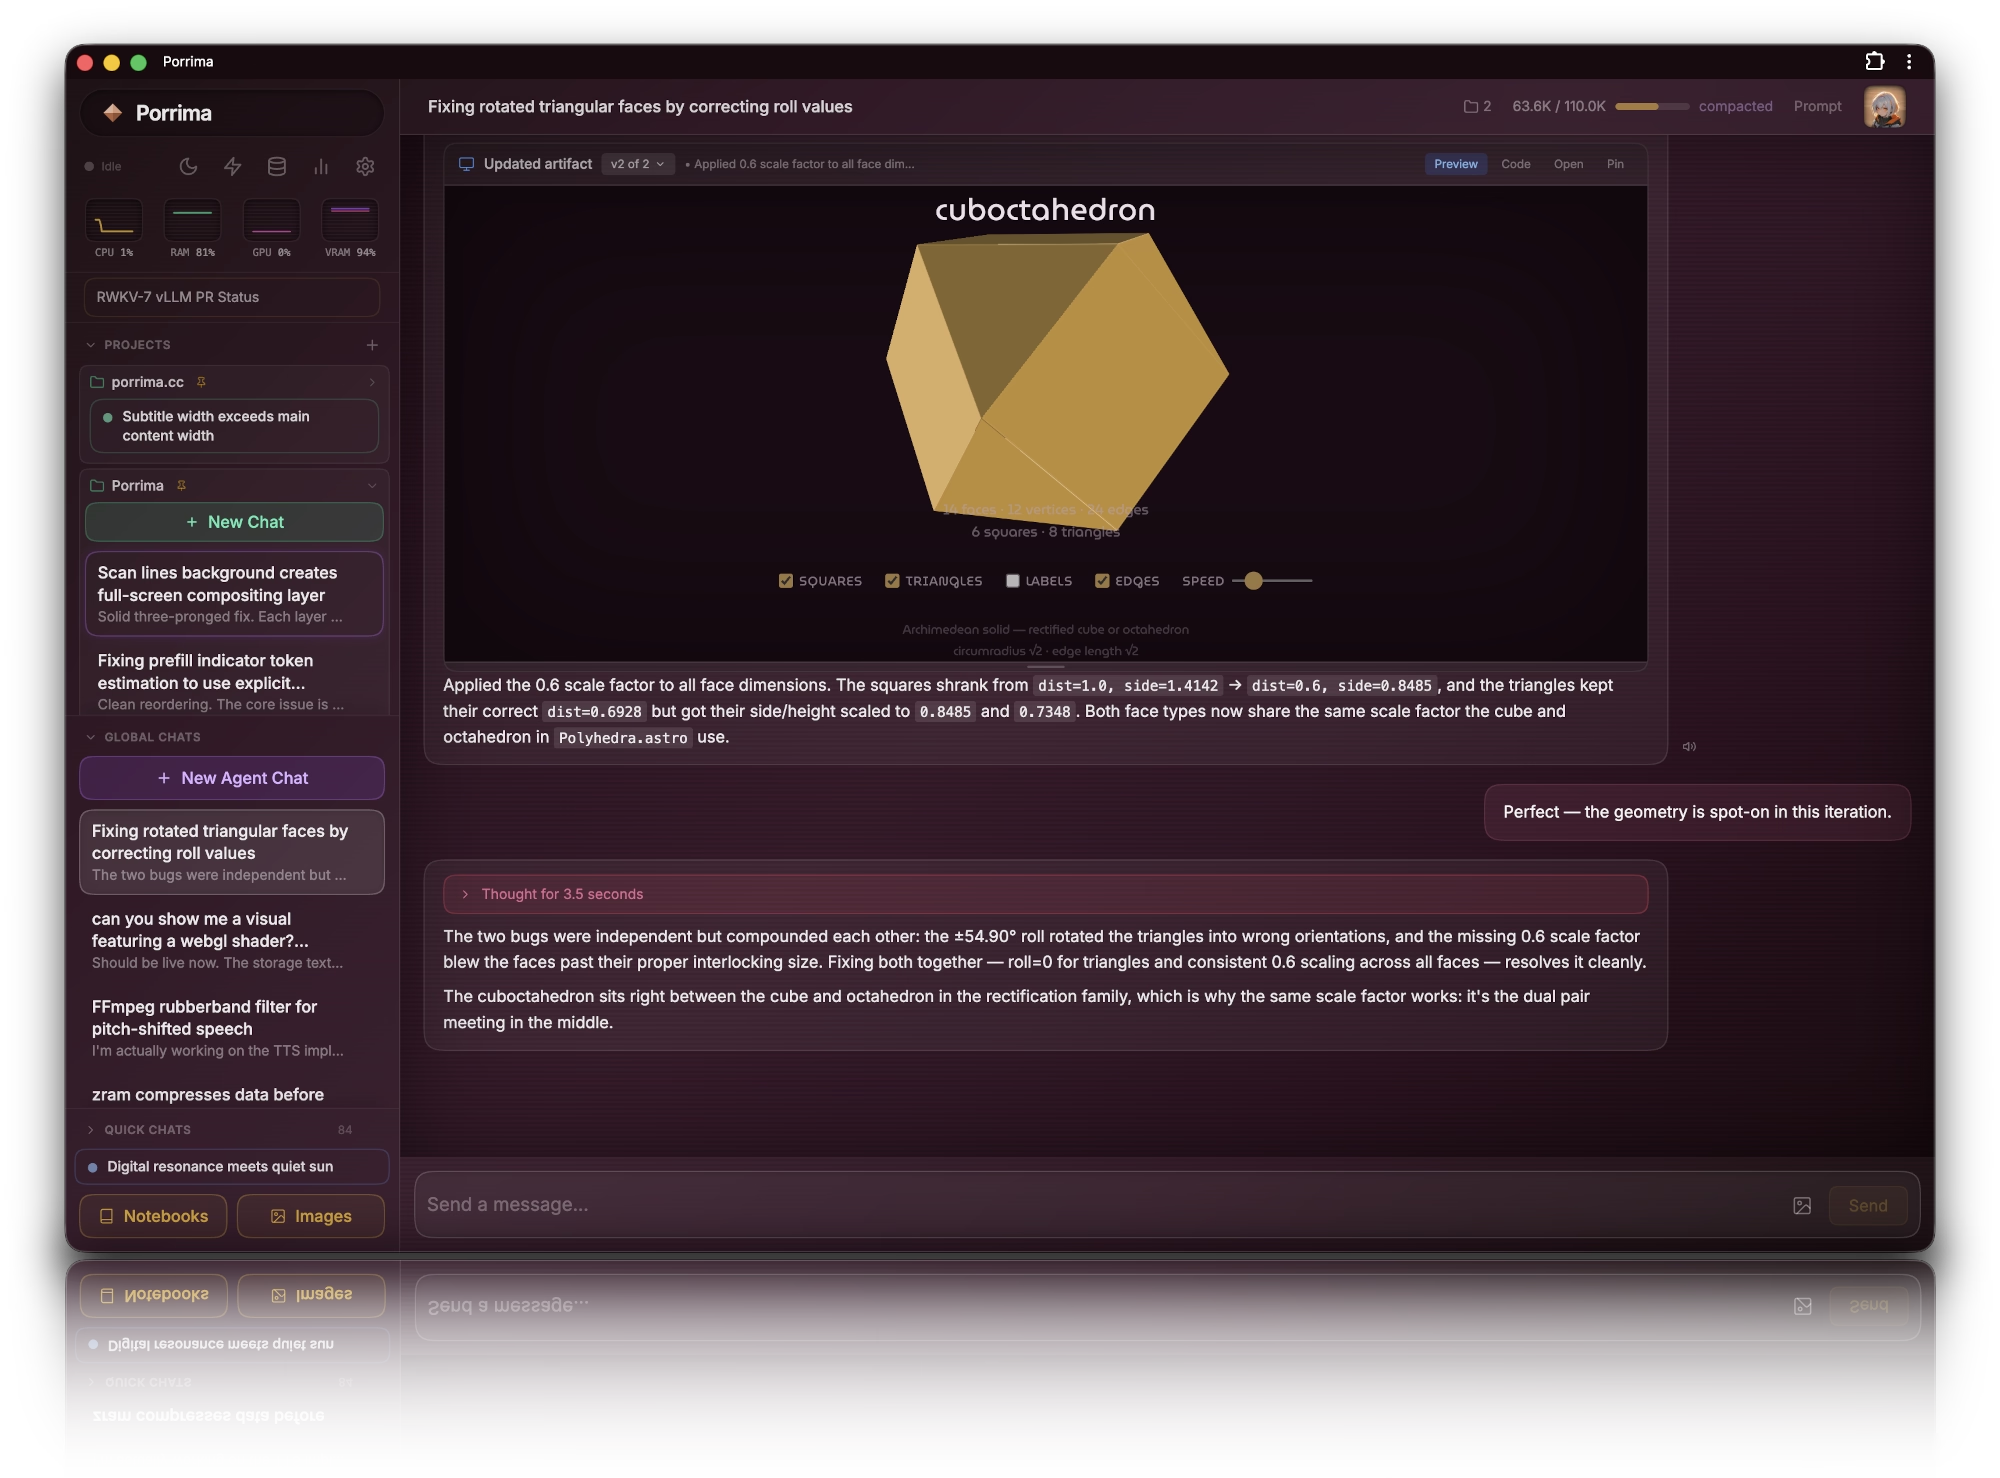
Streaming output with thinking, tool calls, and generated artifacts
Observability and debugging information when you need it: view and manage memory blocks, memory database, model stats, extraction and retrieval runs
Parallel ambient memory
Porrima saves and recalls its experiences both consciously and subconsciously, with bidirectional runtime memory augmentation.
Runs two language models in parallel during operation.
Cache-friendly, endless context with no compaction cutoff.
Multi-tier memory system with self-managed memory blocks, as well as ambient associative memory with the capacity to recall experiential context both in response to user messages, using memory tools, and spontaneously while it runs, with non-blocking live context injection between tool calls.
Memory extraction model operating in the background takes a first and second pass over the same context as the main model, recording memories of everything new, supersession chains for everything old, to form a database of atomic memories for subconscious recall.
Reviews its recent memories during regular synthesis cycles, and incorporates its experiences into self-managed memory blocks which exist globally and for project scopes, attached to the starting context for chats in the respective scope.
Autonomy
Sleep/wake cycle sets aside non-interactive time for synthesizing its experiences, managing its memory blocks, pulling at threads of curiosity, or whatever else you configure as an automation.
Modular foundation
Manages five hot-swappable Llama.cpp server instances with flexible configuration options in the settings GUI.
Bring your own binaries, including mainline or any Llama.cpp forks of your choosing, separately tuned for your GPU and CPU as needed.
Bring your own GGUFs for each of the main chat, memory extraction, title generation, cross-encoder reranker, and embedding models.
Web tools
Porrima can surf the web, search with the included Exa, Tavily, and/or Brave Search providers, and parse a wide variety of PDFs.
Access anywhere
Built for personal cloud.
Speech
Text-to-speech with backend wrappers included for Kokoro, Qwen3-TTS, and Supertonic 3.
Configure voices, speed, boundary detection, text preprocessing, and apply pitch shift post-processing.
Supports streaming output with Qwen3-TTS, and chunked live playback for Kokoro and Supertonic 3.
Asynchronous thinking space
Features a notebook section where you can write down anything on your mind that you want your agent to see, but doesn't elicit an immediate response. Your agent will read your notes later, and then write notebook entries of its own after reflecting on its recent experiences, as well as things that you wrote.
Backup and restore
Keep an extra copy of your chat history, memory database, and embeddings, and rewind to a previous state with one-click backup and restore. All data is conveniently stored in SQLite databases.
Made for consumer hardware
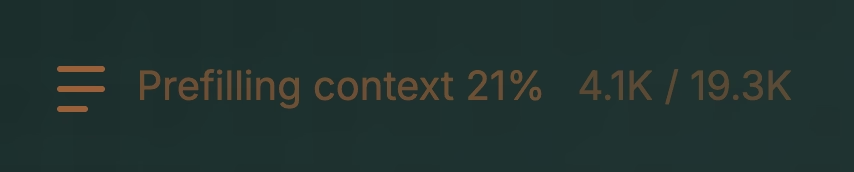
Agent harness designed to be LCP cache-friendly with compaction-time memory consolidation. Includes prefill progress indicators, multi-slot aware cache warmth indicators in the chat list, a cache warmer button, and post-synthesis auto-rewarming for recent chats with busted caches following synthesis cycles.
Context continues indefinitely with no hard breaks, maintaining continuity with the tail of the previous context intact after compaction.
Hardware observability
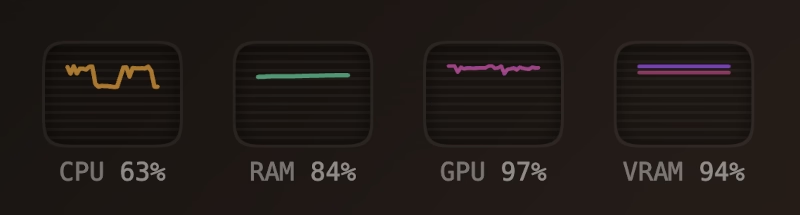
Balance the processing and memory load with built-in llama.cpp server configuration, view inference speed stats, reranking latency stats, and keep an eye on your system resources with the graphical hardware monitor.
Local-only
All data stays on your machine, with networking on your own terms.
Trusted personal AI
Maintain full sovereignty over data, model, infrastructure, and operation. Safe from deprecation, surveillance, and censorship.
Recommended use cases
Software engineering: Porrima is excellent at coding, learns your projects over time, and has a memory system that affords high context-density.
Personal agent: Porrima can do anything on your computer that's accessible by command line.
Research: keeps going down rabbit holes and writing about findings while you sleep.
Companion or advisor: complete privacy, long-term permanence, no topical restrictions.
Artifacts
Porrima can generate HTML artifacts and visuals with a versatile renderer supporting many JavaScript frameworks, see them rendered, make changes autonomously.
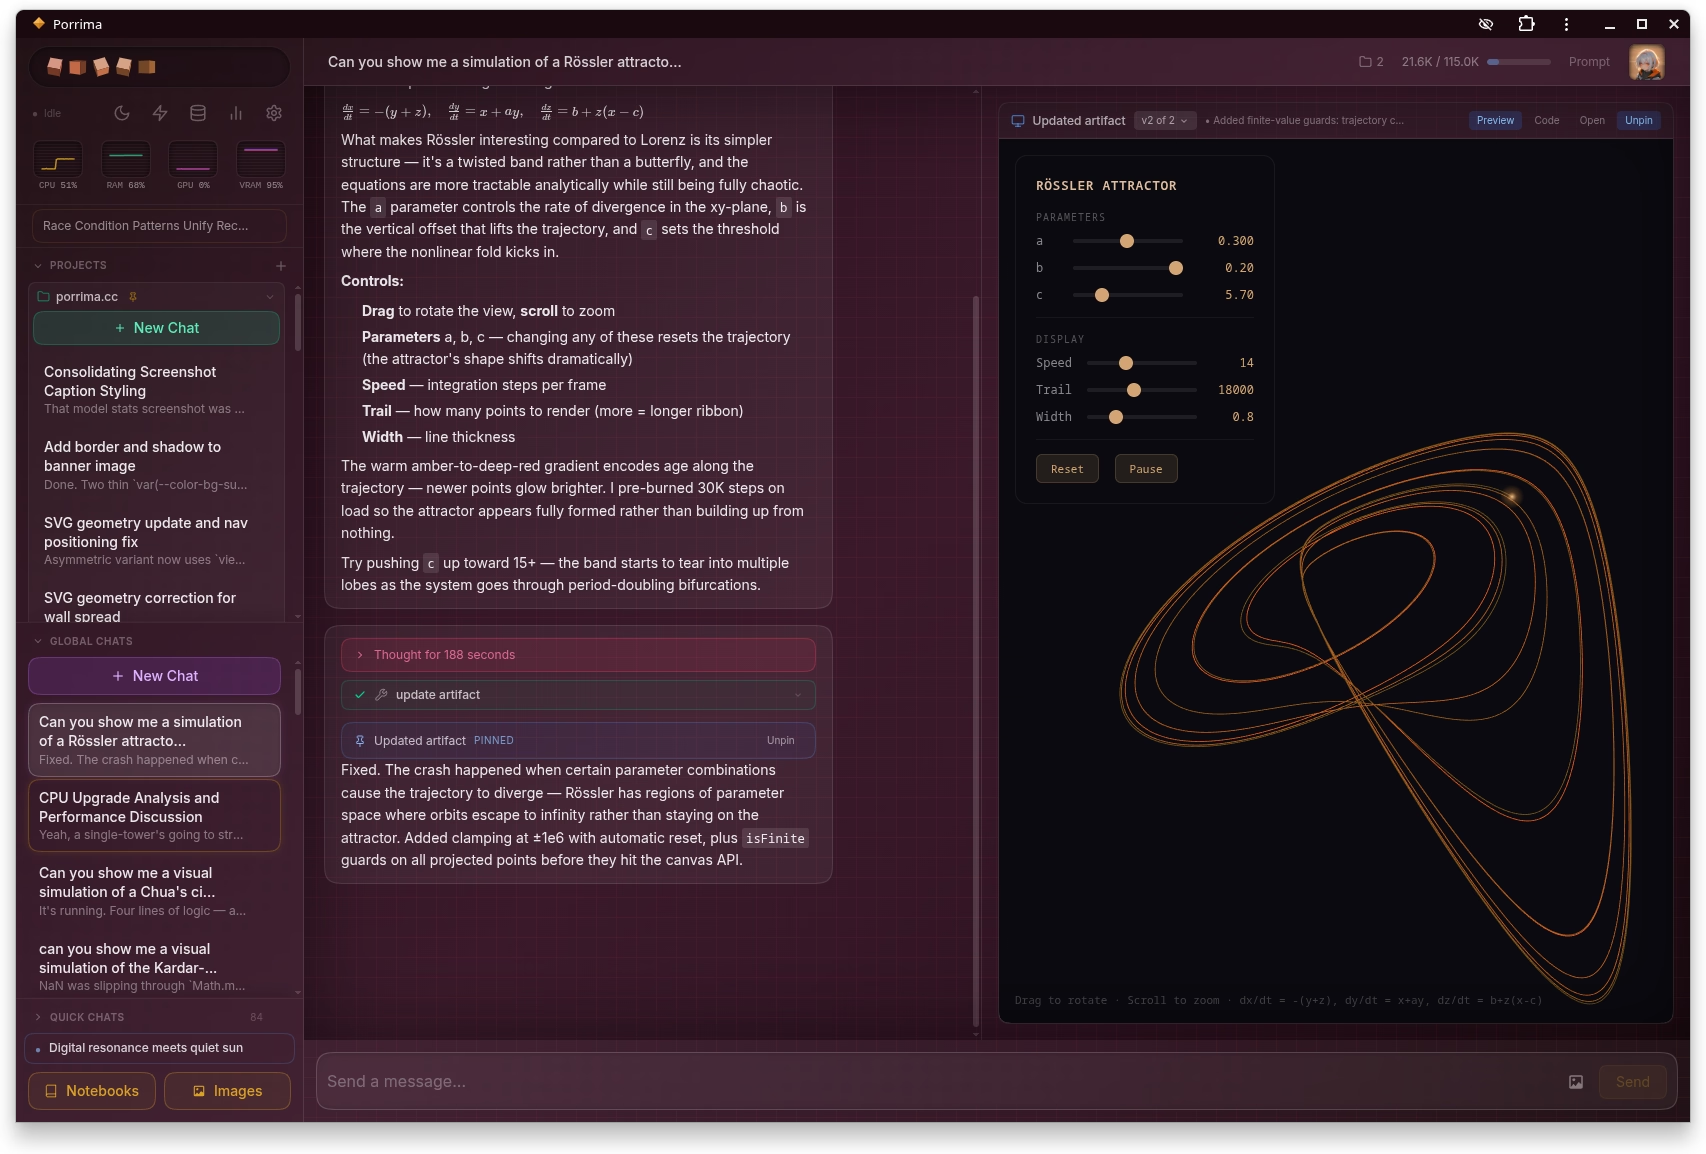
Autonomous artifact vision and repair
September 2026
- Main
- Qwen 3.8 27B
- Memory Extraction
- Qwen 3.5 9B/4B
- Title Generation
- Gemma 4 E4B or Gemma 4 E2B
- Reranker
- Qwen3-reranker 0.6B
- Embeddings
- Qwen3-embedding 4B
- OS
- Linux with systemd
- GPU
- ≥32GB total dedicated VRAM, AMD RDNA 3 or later, Nvidia Ampere or later
- CPU
- Desktop-grade x86_64 with ≥8 physical/performance cores, AVX-512 support, AMD Zen 4 or later, Intel Alder Lake or later
- RAM
- ≥48GB dual-channel DDR5
- SSD
- NVMe Gen 4 or 5
- OS
- Linux, MacOS, Windows, Android, iOS
- Browser
- Chromium-based browser with PWA support recommended (mobile Safari also works)
Pass the installation prompt to your existing agent to probe your hardware, install dependencies, and configure everything. Read the installation guide to get running.
What is this?
Porrima is a general-purpose stateful agent framework, memory system, and UI, designed for single-user deployment on consumer hardware.
Is this a plugin, wrapper, or extension that fits into some existing platform?
No, it is a full-stack client + server application built on Llama.cpp.
Where does the name come from?
38 light-years from Earth, Porrima is a binary star system seen from our night sky in the constellation Lyra. The star system takes its name from the Roman goddess of foresight and the future.
Can I take it apart and reuse the code or ideas for something else?
Yes.